

Guides
Step-by-step proxy and web scraping guides: fix 403 blocks and anti-bot challenges, control browser TLS fingerprints, and keep your crawler running.
Playwright Proxy Sessions in Python: Isolate Contexts, Keep IPs Stable
Use Playwright proxy sessions with one sticky token per browser context. Copy a complete async Python example, verify exit IPs, and troubleshoot common failures.
Read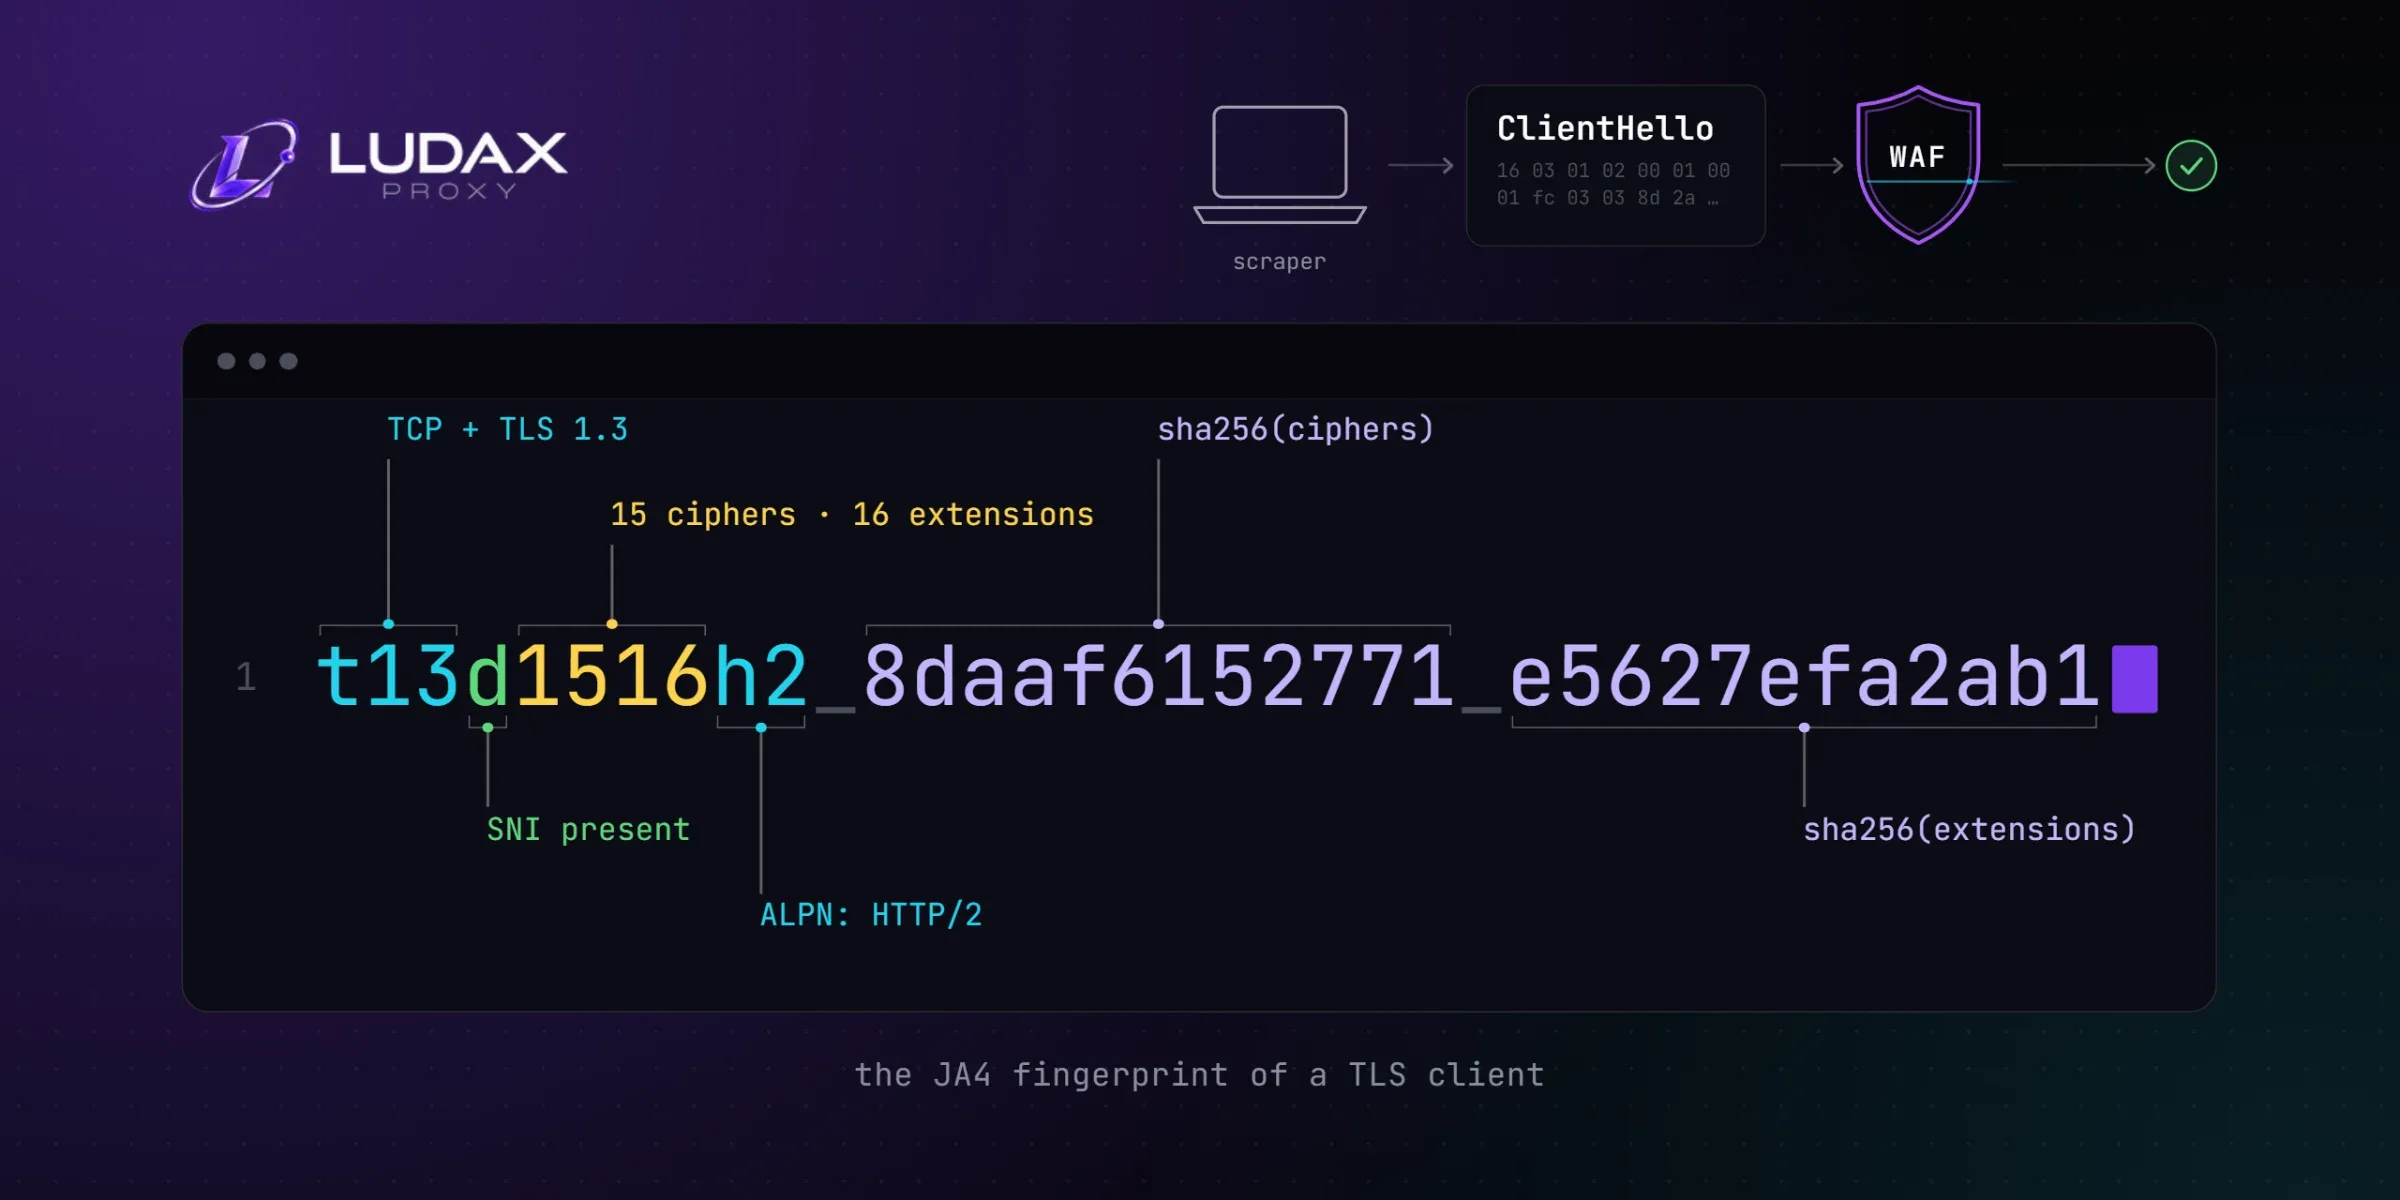
JA4 Fingerprints Explained: How Sites Detect Your HTTP Client
A JA4 fingerprint summarizes your TLS ClientHello in 36 characters, and anti-bot systems match it before any HTML loads. See real JA4s for Python, curl and Chrome from one machine, learn to read every part of the string, and check your own in one command.
Read
Rotating vs Sticky Proxies: Which Session Type Should You Use?
Learn when to rotate IPs and when to keep one session. Use real workload examples, simple Python tests, and cost checks to choose your proxy setup.
Read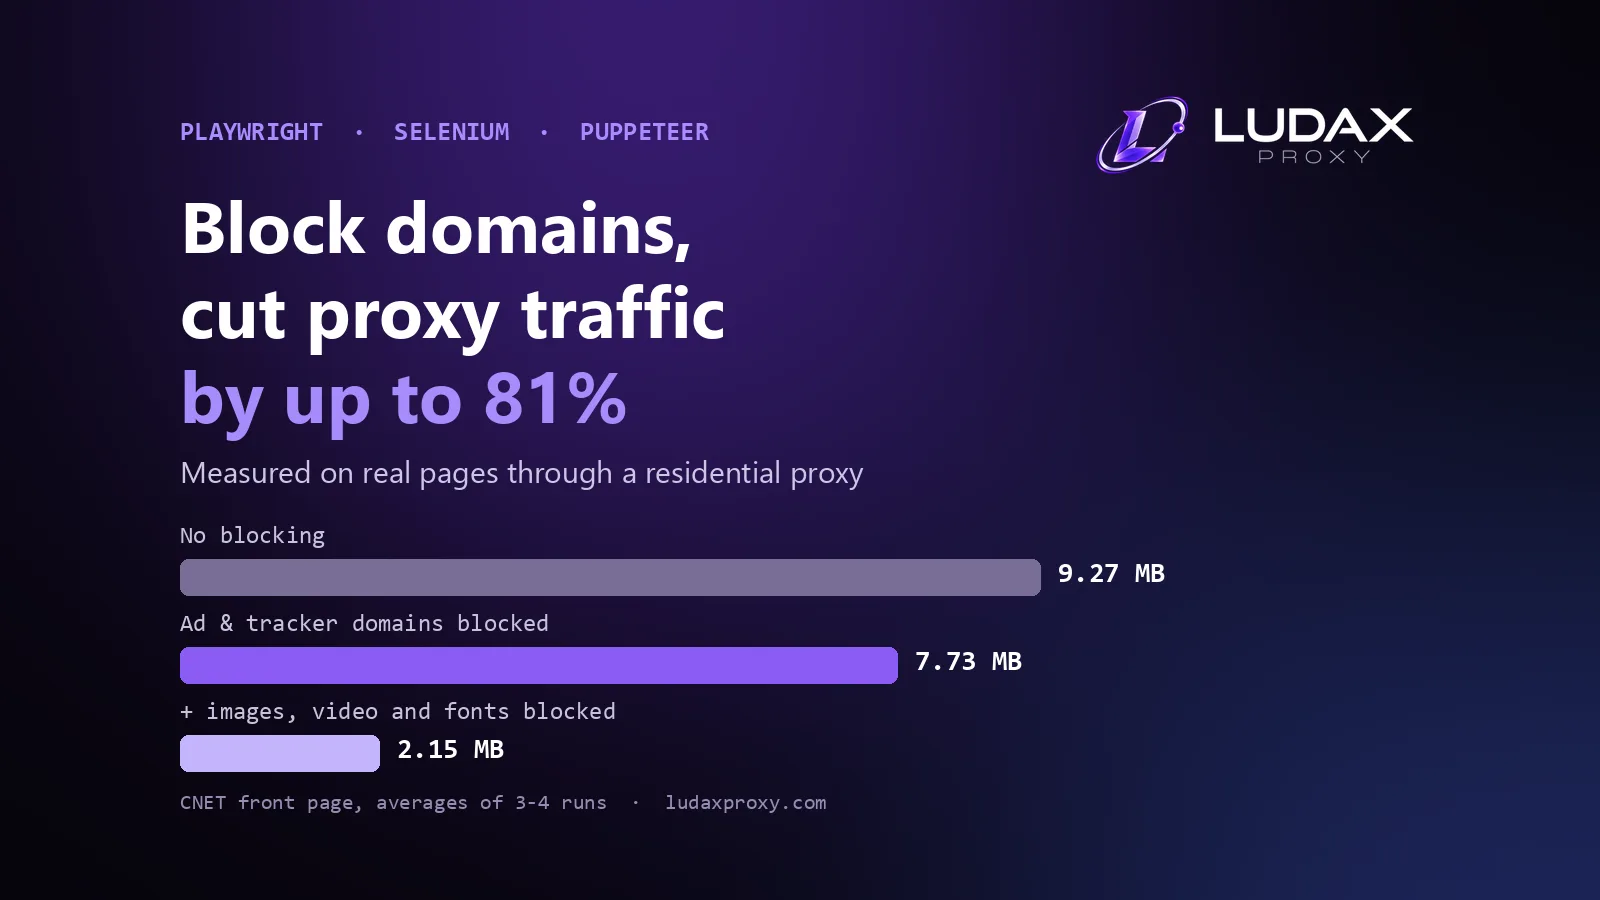
Block Domains in Playwright & Selenium: Cut Proxy Bandwidth by Up to 81%
We loaded three real news pages through a residential proxy with Playwright and measured every byte. Blocking ad and tracking domains cut traffic by 17–29%; adding images, video and fonts cut it by 58–81%. Here is the code for Playwright, Selenium and Puppeteer, how to block at the proxy itself, and what each use case should never block.
Read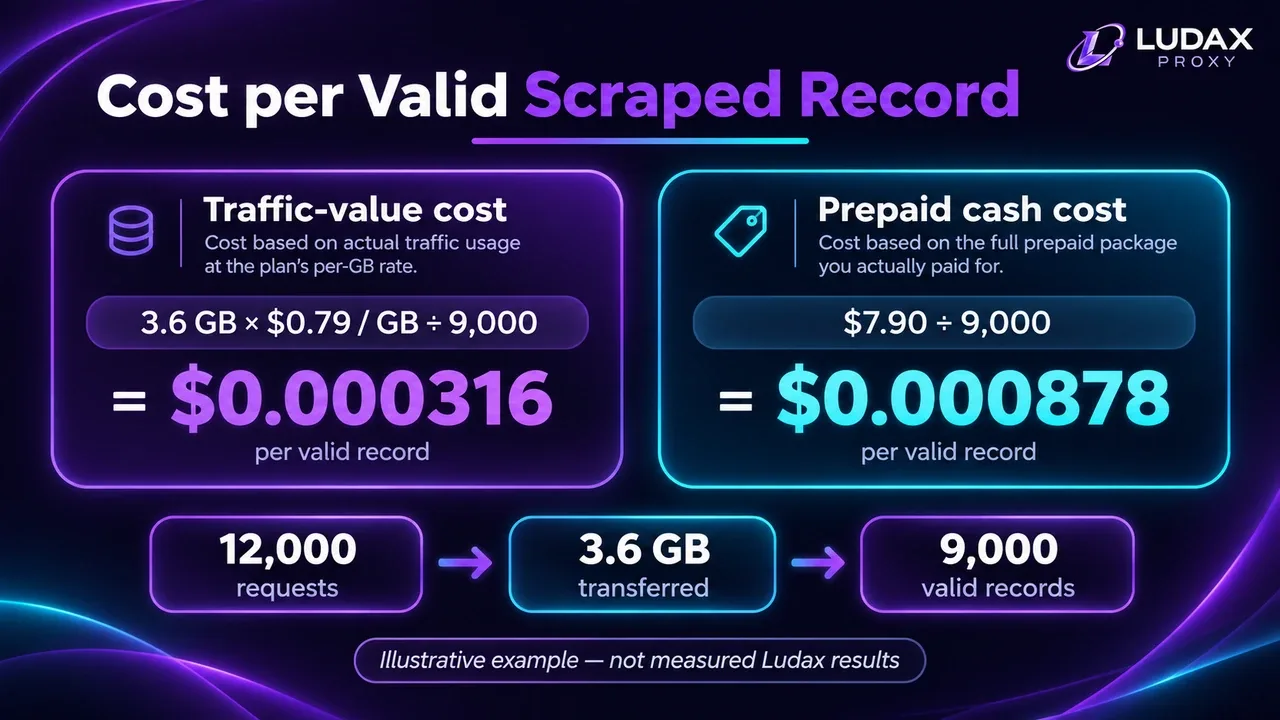
Proxy Bandwidth Cost per Scraped Record: Calculate What Each Usable Result Costs
Learn the real cost per valid scraped record. Compare prepaid cash spend with metered bandwidth, benchmark your workflow, and calculate costs in Python.
Read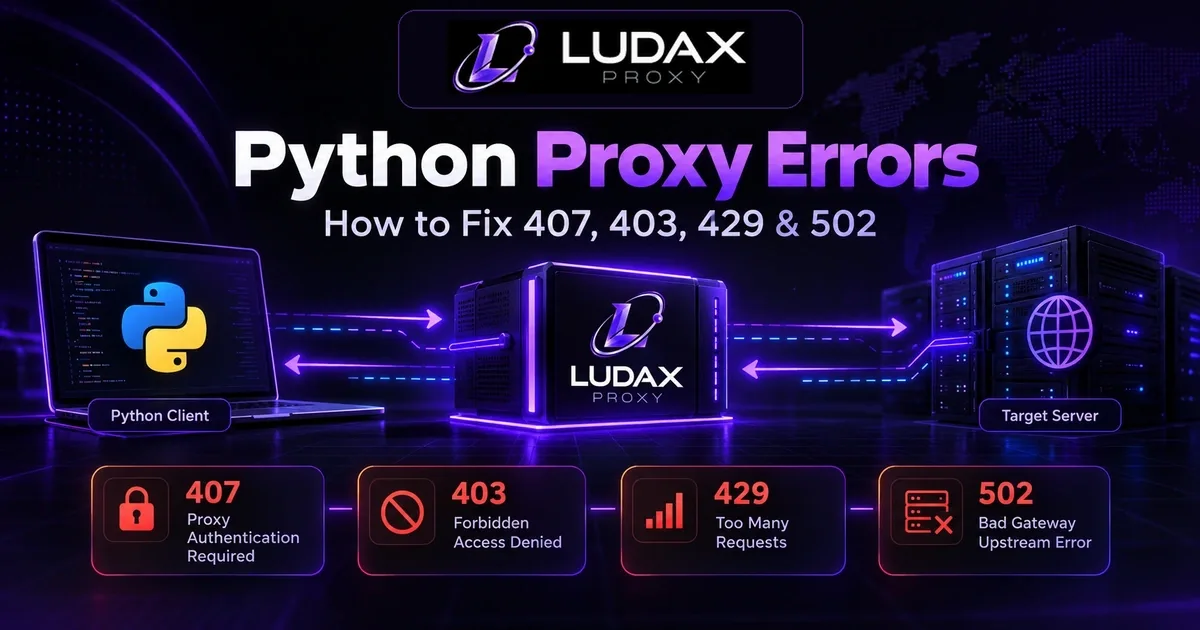
Python Proxy Errors: How to Fix 407, 403, 429 and 502
Diagnose Python proxy errors 407, 403, 429 and 502, pinpoint the failing hop, and fix requests safely using a complete diagnostic script.
Read
Python Price Monitoring with Residential Proxies: A Practical Tutorial
Build a Python price monitor with practical requests and Beautiful Soup code, CSV history, validation, and optional residential proxies.
Read
How to Bypass Cloudflare WAF in 2026: From 403 to 200
A tested Cloudflare WAF bypass for web scraping: read the 403 challenge response like a diagnostic, fix the TLS and HTTP/2 fingerprints that give your crawler away, and get a 200 with a Chrome profile — no headless browser.
ReadRead it, then run it.
Every guide works against the same gateway you get with any plan.